GPU Cloud & Infrastructure
Tarun Tiwari
Head of Product · Nava
Built the Alexa AI platform behind 100M+ devices. Now builds the GPU cloud and training-cluster infrastructure that AI teams run large models on.
MIT · IIT Kharagpur
An in-person cohort on Inference Engineering & AI Infrastructure, led by engineers who run inference in production.
20Weeks
Across 20 weekends
In-person
Bengaluru, India
5Instructors
Active industry engineers
₹999
To apply — fully refundable
Why This, Why Now
75%
Of all AI compute will go to inference by 2030, up from roughly half in 2025.
McKinsey, 2026
50–65%
Gross margins on AI-native products, versus 80–90% for SaaS. The gap is inference efficiency.
AI Startup Benchmarks, 2026
₹70L–1.6Cr
Total compensation for senior inference and GPU-systems engineers in India.
India Market Data, 2026
“The engineering discipline behind it is vastly underappreciated, poorly understood, and frankly, undersupplied with good engineers.”
The Cohort · Instructors
GPU Cloud & Infrastructure
Tarun Tiwari
Head of Product · Nava
Built the Alexa AI platform behind 100M+ devices. Now builds the GPU cloud and training-cluster infrastructure that AI teams run large models on.
MIT · IIT Kharagpur
LLM Systems & Retrieval
Ashish Prasad
Eng. Manager, AI/ML · Microsoft Turing
Helped put GPT-5 inside Microsoft 365 Copilot, working with a team of 30 across engineering and research.
NIT Karnataka
Inference & Serving
Shubhendu Shishir
Head of Engineering · Simplismart
Runs the engineering behind one of the fastest inference engines in production.
NIT Jamshedpur
Agents & Evaluation
Naman Vats
Senior Software Engineer · Sentient Labs
Published research on why the same AI model can cost 40× more to run depending on how you build around it.
BIT Mesra
Model Training & Fine-Tuning
Mayank Sharma
AI Lead · Opkey
Trains models from scratch, and has led ML teams building for images, language and on-device AI.
UT Austin · BITS Pilani
Phase-by-Phase Curriculum
Five phases across 20 weekends, taking you from how a model executes to a production serving system you defend in front of a panel.
Phase A · 01 / 05
Weeks 1–4
Understand how a model executes, then establish the quality and performance baselines every later optimisation is measured against.
Phase B · 02 / 05
Weeks 5–6
Reason from GPU compute, memory and interconnect constraints before touching engine internals.
Phase C · 03 / 05 · core
Weeks 7–14
One continuous block from engine internals to measured single-node optimisation. The core of the program.
Phase D · 04 / 05
Weeks 15–18
Scale the runtime past one GPU, then build the serving platform that deploys, routes, observes and recovers it.
Phase E · 05 / 05
Weeks 19–20
Add the adaptation and application layers the job needs, then defend the whole system in front of a panel.
Eligibility
Your job title does not matter. If most of these sound like you, apply.
01
2+ years, full-time
Relevant professional work. Internships do not count.
02
ML or applied ML background
Or backend/platform, if you meet the same ML bar.
03
Professional Python
Modular code, testing, debugging, Git.
04
Hands-on PyTorch
Run and modify a model, inspect tensors, use autograd.
05
Transformers at working level
Attention, embeddings, tokenisation, how generation works.
06
Working systems knowledge
Linux, HTTP, concurrency, Docker.
Admission Process
We review applications on a rolling basis. Apply early — seats fill before the deadline.
Pay ₹999 to apply
Secures your interview slot. Fully refundable if you are not shortlisted for the interview.
Fill the application form
Tell us about your background, current role, years of experience, and why you want to join.
Get invited for a 1-on-1 interview
A 30-minute technical and fit interview with one of the instructors, typically within 5 days.
Get selected
We notify you within 24 hours of the interview. If selected, you receive a formal offer letter.
Secure your seat
Pay the ₹5,000 registration fee to confirm your place. Seats are confirmed in order of acceptance.
Complete the admission process
Review the program agreement, set up your tools, and join the cohort Slack before Day 1.
Program fee
Pay ₹999 to apply — the rest is due only once you have an offer and have accepted your seat.
Application fee
₹999
100% refundable if not shortlisted for the interview
What the fee covers
Program fee is refundable as per our Refund & Withdrawal Policy.
Seats are confirmed in order of acceptance.
You pay
₹2,06,500
Inclusive of GST · Single payment
Registration fee(non-refundable)
₹5,000
Program fee(refundable per policy)
₹1,70,000
GST (18%)
₹31,500
You pay
Instalment 1
₹50,000
Instalment 2
₹1,56,500
Flexible plans, no financial stress.
Registration fee(non-refundable)
₹5,000
Program fee(refundable per policy)
₹1,70,000
GST (18%)
₹31,500
You pay
₹37,613/ month × 6
Spread the cost over 6 months.
Registration fee(non-refundable)
₹5,000
Program fee(refundable per policy)
₹1,70,000
GST (18%)
₹31,500
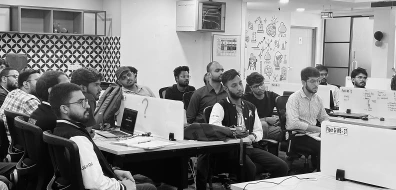
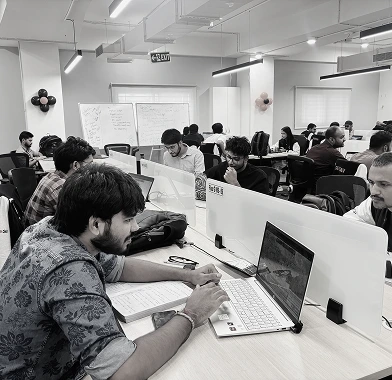
Offline Experience
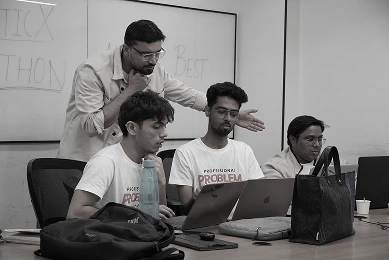
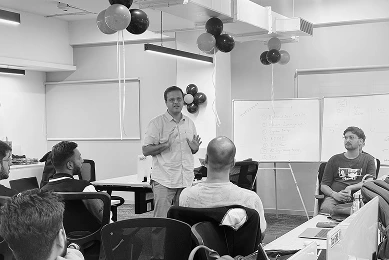
Step away from zoom screens. Build production-grade inference pipelines shoulder-to-shoulder with elite systems engineers.
Apply
Applications for the November cohort are open.
Selective admission · ₹999 to apply · Fully refundable if not shortlisted
FAQ
All 240 guided hours, live weekend sessions, project reviews, capstone mentorship — and the GPU compute you use throughout. Every lab, benchmark and capstone run happens on machines we provide, so there is no separate cloud bill. You just need your own laptop.
In three stages. ₹999 when you apply, which secures your interview slot. If you are selected, a registration fee of ₹5,000 confirms your seat. The balance is due before the first weekend, and you can pay it upfront, in two instalments, or as 6 monthly EMIs through our NBFC partners.
Yes. This one is ML-first: you should already write production Python, work comfortably in PyTorch, and understand how transformers generate text. Backend and platform engineers are welcome, but they meet the same ML bar rather than substituting systems experience for it.
Six hours on Saturday, six on Sunday, plus about 30 minutes a day during the week. About 320–360 hours in total.
Yes. That is what the weekend format is for — we expect everyone to be working, and the weekday work is built to fit around a job.
Sessions are recorded, so missing one is fine. Miss several in a row and your project deadlines slip, so we would work out a plan with you.
You will understand an open LLM, make it faster and cheaper, and run it as a reliable production service.
No. This is for engineers who already have jobs. What you get is proof you can run LLM systems in production — the four projects.